

 Login


 September 25, 2026
|
Voiced by Amazon Polly |
Foundation models have transformed the field of artificial intelligence by providing a versatile base for a wide range of applications, from text generation and code completion to image creation and scientific research. These large-scale models are trained on massive datasets using self-supervised learning, enabling them to perform multiple downstream tasks with minimal additional training. As businesses continue adopting Foundation Models to automate workflows and improve decision-making, understanding their technical architecture and capabilities has become increasingly important.
Start Learning In-Demand Tech Skills with Expert-Led Training
- Industry-Authorized Curriculum
- Expert-led Training
What Are Foundation Models?
Foundation models are large neural networks trained on broad, diverse datasets instead of task-specific data. Unlike traditional machine learning models that are designed for a single purpose, foundation models learn generalized representations that can be adapted to various applications through fine-tuning, prompt engineering, or retrieval-augmented generation (RAG).
Examples include transformer-based language models, multimodal models that process text and images, and domain-specific foundation models designed for healthcare, finance, or software development.
Core Architecture
Most modern foundation models rely on the Transformer architecture, introduced in the landmark research paper Attention Is All You Need. The transformer replaces recurrent neural networks (RNNs) with a self-attention mechanism, enabling efficient parallel processing of input sequences.
The architecture primarily consists of:
- Embedding Layer: Converts words or tokens into dense vector representations.
- Positional Encoding: Adds sequence information since transformers process tokens in parallel.
- Multi-Head Self-Attention: Captures relationships between tokens regardless of their distance in the sequence.
- Feed-Forward Neural Networks (FFN): Apply nonlinear transformations to improve feature learning.
- Layer Normalization and Residual Connections: Enhance training stability and allow deeper architectures.
This design allows models to scale efficiently while maintaining strong contextual understanding.
Training Process
Foundation models undergo several stages of training:
- Data Collection
Training data typically includes:
- Books
- Research papers
- Websites
- Programming code
- Public documentation
- Images and multimedia (for multimodal models)
The objective is to expose the model to diverse linguistic patterns and knowledge domains.
- Tokenization
Instead of processing raw text, models divide text into smaller units called tokens using algorithms such as Byte Pair Encoding (BPE) or SentencePiece. This significantly reduces vocabulary size while maintaining language flexibility.
- Self-Supervised Learning
Unlike supervised learning that requires labeled datasets, foundation models learn by predicting missing or next tokens. Common objectives include:
- Next-token prediction
- Masked language modeling
- Contrastive learning
- Image-text alignment
This approach enables the model to learn grammar, reasoning patterns, semantic relationships, and contextual understanding without manual annotations.
Scaling Laws
One defining characteristic of foundation models is scaling.
Performance generally improves as:
- Model parameters increase
- Training dataset size grows
- Compute resources expand
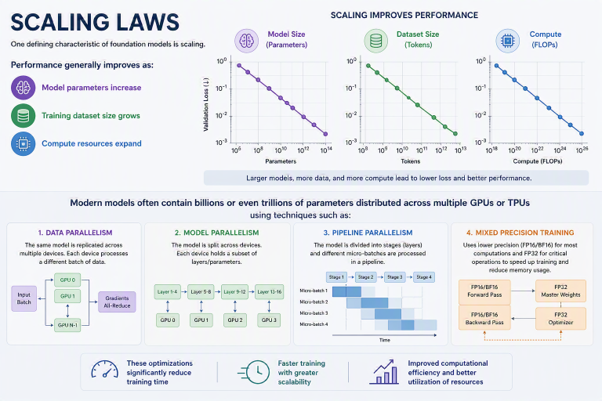
Fig 1: Scaling laws explain how larger models, datasets, and compute improve AI performance.
Modern models often contain billions or even trillions of parameters distributed across multiple GPUs or TPUs using techniques such as:
- Data Parallelism
- Model Parallelism
- Pipeline Parallelism
- Mixed Precision Training
These optimizations significantly reduce training time while improving computational efficiency.
Fine-Tuning and Adaptation
After pre-training, organizations customize foundation models for domain-specific tasks using several methods:
Full Fine-Tuning
All model parameters are updated using task-specific datasets. Although effective, this method requires substantial computational resources.
Parameter-Efficient Fine-Tuning (PEFT)
Modern techniques reduce training costs by updating only a small subset of parameters.
Popular methods include:
- LoRA (Low-Rank Adaptation)
- Prefix Tuning
- Prompt Tuning
- Adapters
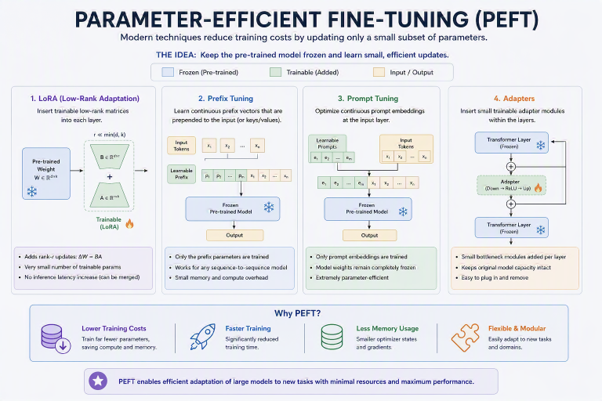
Fig 2: PEFT techniques enable efficient fine-tuning of foundation models with lower training costs.
These approaches allow multiple specialized models to efficiently share the same base model.
Retrieval-Augmented Generation (RAG)
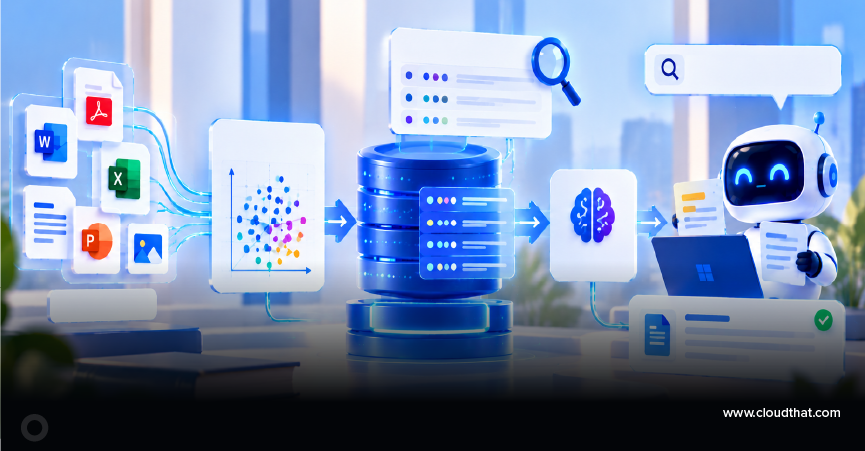
One challenge with large language models is that their knowledge becomes outdated after training. Retrieval-Augmented Generation addresses this by combining external knowledge retrieval with text generation.
The workflow includes:
- User submits a query.
- Relevant documents are retrieved from a vector database.
- Retrieved context is added to the prompt.
- The model generates a context-aware response.
This architecture improves factual accuracy while reducing hallucinations.
Model Evaluation
Evaluating foundation models requires multiple benchmarks rather than simple accuracy metrics.
Common evaluation criteria include:
- Perplexity
- BLEU Score
- ROUGE
- MMLU
- Human Evaluation
- Truthfulness
- Safety
- Bias Assessment
Organizations also monitor latency, throughput, token generation speed, and inference costs during deployment.
Infrastructure Requirements
Training foundation models demands enormous computational resources.
Typical infrastructure includes:
- High-performance GPUs (such as NVIDIA H100 or A100)
- TPUs
- Distributed storage systems
- High-speed networking
- Kubernetes-based orchestration
- ML frameworks like PyTorch or TensorFlow
Cloud platforms often provide scalable infrastructure to support these intensive workloads.
Challenges
Despite their remarkable capabilities, foundation models face several technical challenges:
- High computational costs
- Large energy consumption
- Hallucinated outputs
- Data privacy concerns
- Model bias
- Explainability limitations
- Long inference times for very large models
Researchers continue developing optimization techniques such as quantization, model pruning, knowledge distillation, and efficient inference engines to address these issues.
Future Outlook
The next generation of Generative AI foundation models is expected to become increasingly multimodal, capable of seamlessly processing text, images, audio, video, and structured data within a single architecture. Advances in reasoning, memory augmentation, autonomous agents, and domain-specific customization will further enhance their practical applications across industries, including healthcare, finance, manufacturing, education, and scientific research.
As organizations continue integrating foundation models into enterprise workflows, understanding their technical foundations, from transformer architectures and self-supervised learning to fine-tuning strategies and scalable deployment, will be essential for building reliable, efficient, and responsible AI systems.
Upskill Your Teams with Enterprise-Ready Tech Training Programs
- Team-wide Customizable Programs
- Measurable Business Outcomes
About CloudThat

WRITTEN BY Vivek Kumar
Vivek Kumar is a Senior Subject Matter Expert at CloudThat, specializing in Cloud and Data Platforms. With 11+ years of experience in IT industry, he has trained over 2000 professionals to upskill in various technologies including Cloud and Full Stack Development. Known for simplifying complex concepts and hands-on teaching, he brings deep technical knowledge and practical application into every learning experience. Vivek's passion for technology reflects in his unique approach to learning and development.


 PREV


Comments